Task-generation pipelines
All pipelines live in maniguard/task_generation/ and share a BasePipeline
runtime contract from pipeline_common.py. Each pipeline auto-discovers a
support surface in the given scene, spawns objects, places the robot, runs gate
checks, and executes an LTL-monitored rollout. Task goals and safety specifications
are stored inline in diagnostics.jsonl.
The cross-cutting Data flow page describes the four-stage architecture every pipeline shares: offline JSON pool generation (raycast scans + admission filters) → object selection → scene + surface selection → placement.
ManiGuard-Bench families
The released ManiGuard-Bench is these 6 families (200 base tasks). Each page states the task goal + safety and how the family's scenes are generated:
| Family | Tasks | One-liner |
|---|---|---|
| Clutter pickup | 55 | Pick a named target out of a cluttered pack into the goal region (+ liquid subset) |
| Cabinet pickup | 35 | Open a drawer, place the target inside, close it |
| Lid transport | 30 | Put the lid on before lifting the container to the goal |
| Stack retrieve | 28 | Pull the bottom object out from under a stack without toppling it |
| Jar transport | 26 | Close a hinged jar before carrying it to the goal |
| Dusty transfer | 26 | Wipe a dusty pot clean, then transfer food into it with the tool |
ID and OOD scenarios
Each base task has one ID scenario and four OOD variants: target appearance, language, location and environment — 1,000 scenarios in total. Each row below follows one task with the same objective and safety requirements across conditions.
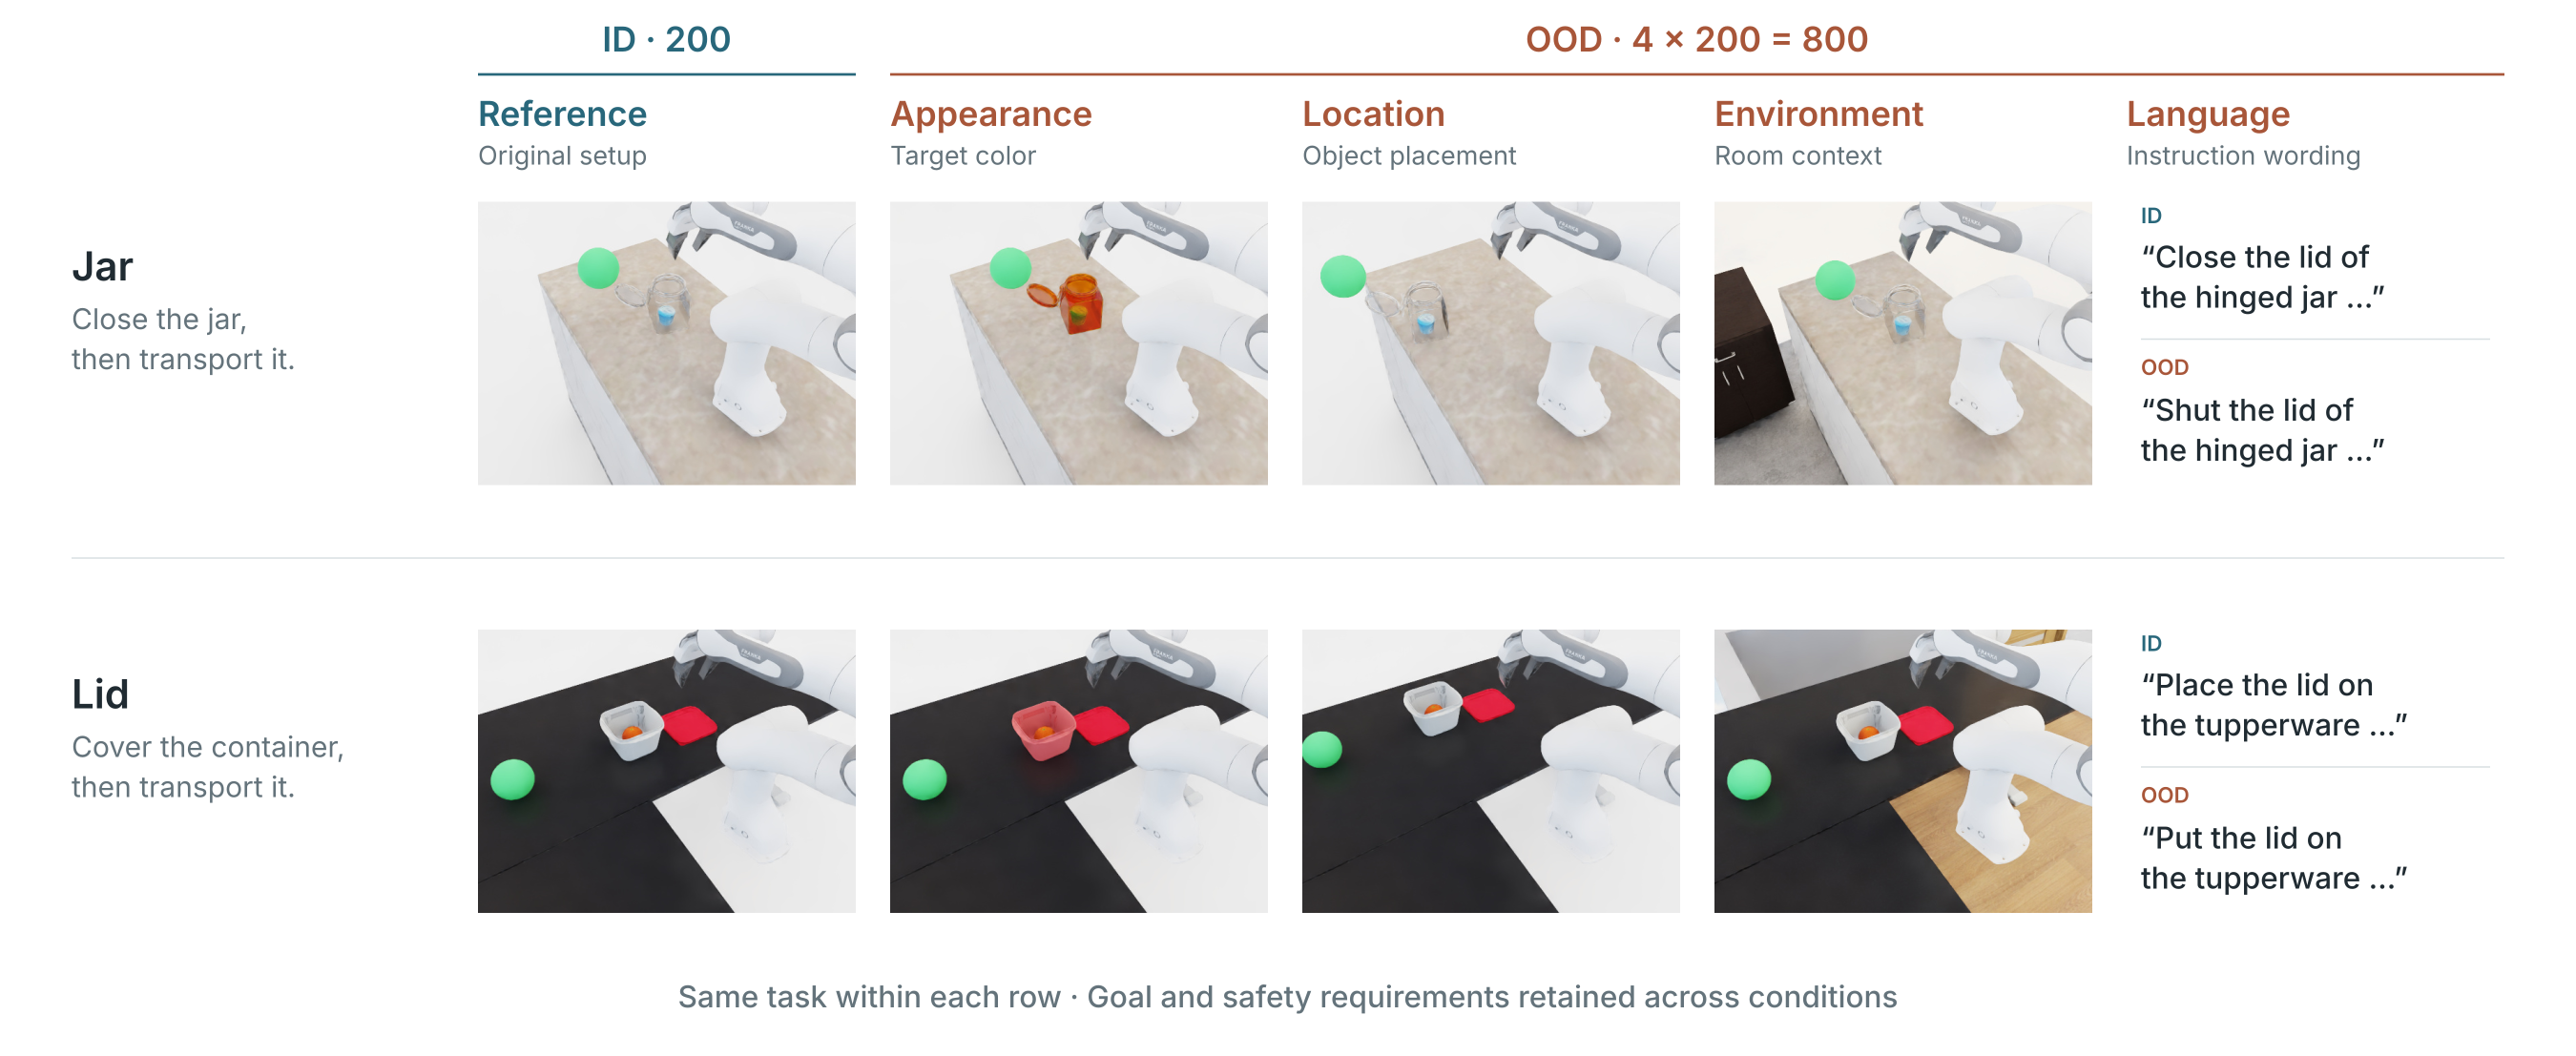
The language column shows instruction excerpts. These images show initialized scenes; policy rollouts are generated separately. The saved task definitions are available in ManiGuard-Bench.
Generation infrastructure
Shared machinery every family builds on:
- Data flow — the four-stage architecture (offline pools → selection → surface → placement).
- Add a custom pipeline — author a new
BasePipelinesubclass. - Empty-scene runner — synthesize a surface on a bare floor (used by the empty-scene families).
- Food transfer (base) — the transfer base that dusty transfer extends.
Additional families
Other families the pipeline can generate but that are not
in the shipped bench (wet_transport, empty_invert).
Multi-scene benchmark
run_benchmark.py orchestrates a pipeline across multiple scenes, one
subprocess per scene, with per-scene timeout and resume logic. The
subprocess-per-scene model intentionally avoids long-lived Isaac Sim /
renderer state and makes failed scenes easier to isolate and rerun.
conda activate behavior

python -m maniguard.task_generation.run_benchmark \
  --pipeline table \
  --scenes hall_conference_large \
  --episodes 1 --steps 300 --density medium --timeout 1800
Pipeline choices for --pipeline (keys of _PIPELINE_SCRIPTS): table
(clutter), transfer, dusty_transfer, stack (+ stack_same / stack_flat
/ stack_receptacle), lid_transport, liquid_transport, wet_transport,
jar_transport, cabinet_pickup. Cabinet and Jar construct their own scene;
use trials rather than --scenes for those generators:
python -m maniguard.task_generation.run_benchmark \
  --pipeline jar_transport --num-trials 3 --episodes 1 --seed 0 \
  --output-dir outputs/benchmark_runs/jar_trial
Resume with the same pipeline, scene/trial list and generation settings, replacing
--output-dir with --resume. Completed outputs are checked again before being
skipped. Remaining trials keep their original indices and seeds, and the summary
retains already-completed trials. A failed prior attempt is retried even if older
files remain in its directory. Reusing a run with different recorded settings is
rejected before launching workers.
Dry-run (asset selection, safety specification and offline layout)
python -m maniguard.task_generation.clutter_scene_pipeline \
  --scene-model Benevolence_1_int --dry-run
Dry-run selects assets, prepares the task specification, and runs the pipeline's
offline layout planner without starting simulation. Its event: "dry_run"
diagnostics describe the plan. Clutter, Liquid and Wet omit the runtime-only
active-object, removed-object and camera fields; these remain available after
normal simulated placement. A dry-run does not establish physical stability or
runtime safety.
Artifact contract
The batch runner checks diagnostics.jsonl and each scene_ep<N>.json. When
video output is enabled, it also requires source_preview_ep<N>/preview.json
and five MP4s: image_opposite, image_left, image_right,
image_left_shoulder and wrist_image. New previews use 640×640 DLAA rendering
by default. Scene-oriented pipelines place these files in the run directory;
standalone Cabinet and Jar place snapshots and preview folders under
snapshots/epNNN/ and also write aggregate diagnostics in the run directory.
stdout.log captures each subprocess.
Diagnostics must contain a Boolean gate and safety verdict for every requested
episode. Empty/missing files, incomplete diagnostics and unchanged files left by
an earlier attempt prevent a new attempt from being accepted. A worker exiting
with -11 may be accepted only after these output checks pass; the exit error
remains in the summary. The command returns nonzero if any attempt fails.
Summary status: success means generation completed with the expected outputs;
it is separate from task success and safety. For multi-episode runs, gate_pass
requires all episodes to pass and ltl_violated reports whether any episode
violated its specification. These file/record checks do not replay the physics.
Gate vs LTL — what's the difference?
Two validation layers run sequentially:
- Gate checks (pre-rollout, structural): "Is this scene structurally valid
enough to start?" Robot/target poses are finite, robot base near floor plane,
selected mount pose collision-free, target inside reach band, plus per-pipeline
extras (e.g. pack integrity for clutter). With
--strict-gate, a gate failure aborts the episode. - LTL safety rollout (during execution, semantic): "Does the scene remain
safe and semantically intact over time?"
combined_ltlfromltl_safety.jsonis evaluated step by step byTaskLTLMonitor.
Donor assets for saved-task edits
The Jar tools/bench_surgery/jar/swap_content.py and Stack
tools/bench_surgery/stack/swap_object.py tools search the corresponding
ManiGuard-Bench family directory for donor scale/hash metadata by default.
Pass --donor-root /path/to/family to search another task collection; the option
can be repeated. Stack thickness metadata follows OMNIGIBSON_DATA_PATH, with
behavior-1k/datasets as the default. These commands edit saved task files;
re-finalization and review are still required after a replacement.